How to optimise your model
When to optimise your model
As a general guide, you would usually consider optimising your model when you are hitting consistent memory usage of greater than 90%. This is especially important if your memory usage will likely only increase, as users update budgets, or overnight loads occur bringing in additional datapoints from external databases and systems.
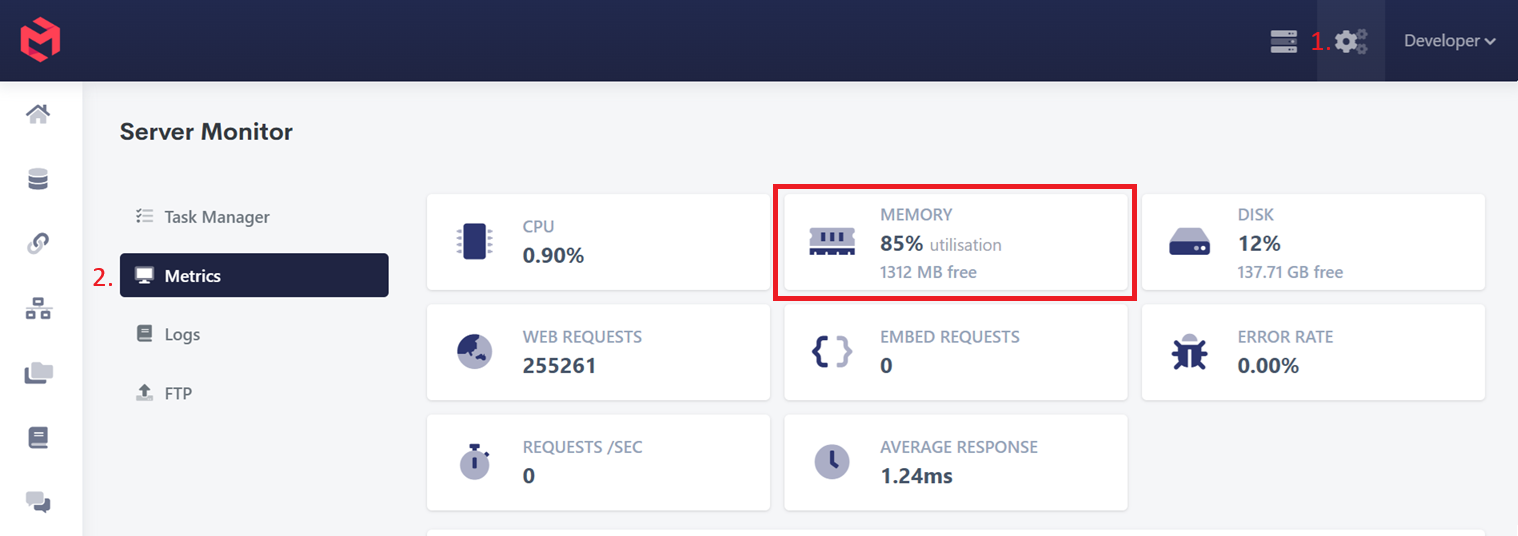
This can be found by opening your model logs on go.modlr.co, and accessing your model metrics.
If you are seeing real world impact, it's time to consider optimising your model, regardless of the exact memory usage percentage reported.
Knowing which cubes are worth optimising
Not every cube is worth your time. You might have a cube with inefficient formulas, but if it only contains 1,000 cells out of a total model size of 100,000,000 cells, optimising it will not achieve much.
To make an impact, you need to find your largest cubes in terms of cell count.
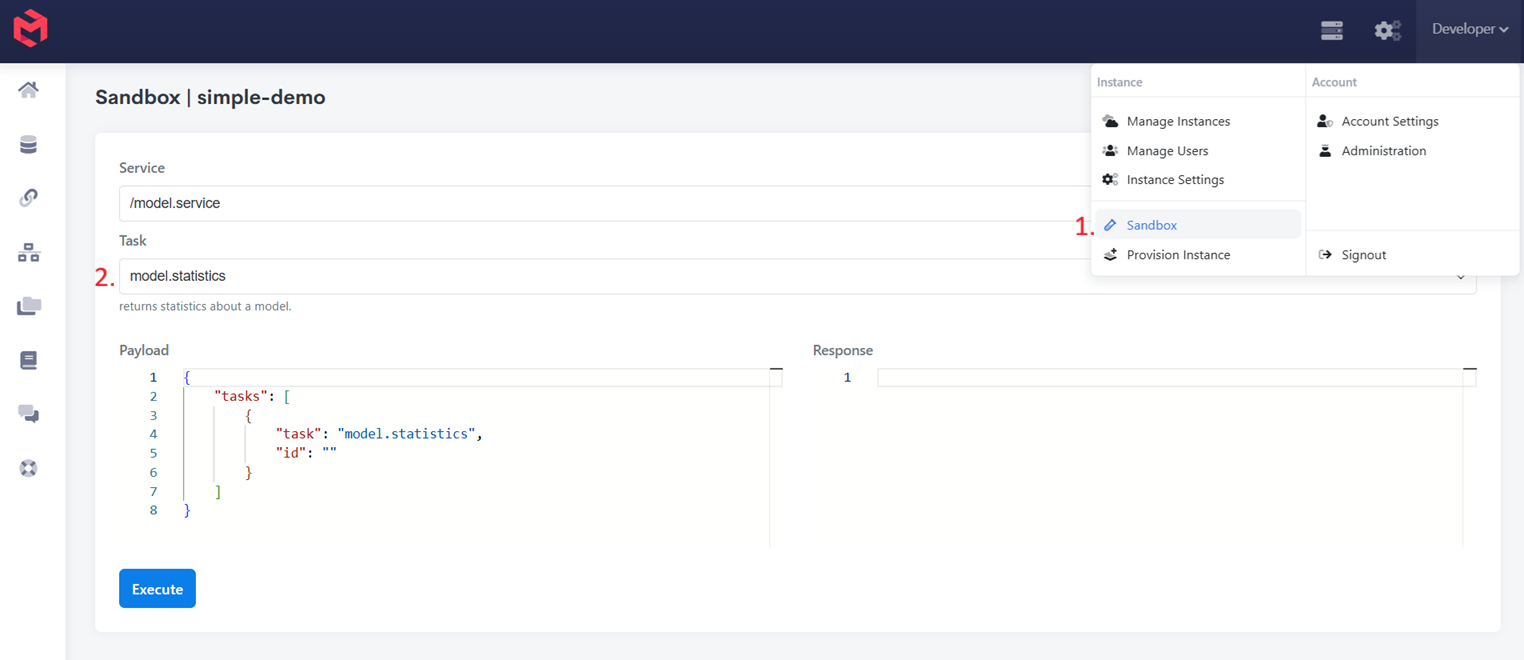
- Open Sandbox
- Run the task
cube.statisticsunder service/model.service
What does it mean to optimise your model
When we talk about optimising your model, the most common way to do this is to reduce your model's cell count. Each cube has an amount of fed cells, and to reduce this usually involves one of the below:
- Restricting formulas
- Turning off unnecessary feeders
- Removing unused old data
Restricting formulas
Ensure formulas are restricted appropriately. For example, if a formula should only apply to a single scenario, and it is not restricted, it should be restricted to that scenario.
Step by step guide on how to restrict a formula.
Turning off unnecessary feeders
Feeders are one of the simplest fixes, yet one of the most impactful causes of cell count balloon.
For more details on turning off feeders, please review the documentation on Turning off a feeder.
Removing unused or old data
Too much old data that is unused adds unnecessary size and cell count to your model. Consider:
- Is there data from years ago that is no longer required in MODLR memory? Should it be stored in the MODLR data warehouse, or wiped entirely?
- Are there old scenarios that have never been used?
These are all considerations worth asking when reviewing your model.
Step by step guide on how to remove data from a cube.
TIP
MODLR will retain the cell location in memory until the server has been restart. Please ensure you restart your server to see the impact of your optimisations.
Why sparsity usually isn't something to worry about
A Cube's theoretical size is the product of its dimension sizes - five dimensions of 50 elements each is 50⁵, over 300 million possible intersections. In practice only a small fraction of those ever hold data: most combinations are meaningless (a given store doesn't sell every product every day), and the ratio of populated cells to possible cells is called sparsity. Most real business cubes are extremely sparse, often populated at well under one percent.
MODLR doesn't store empty cells, and the calculation engine only traverses populated space - a cube with 300 million possible cells but 200,000 populated ones costs memory and computation proportional to the 200,000, not the 300 million. This means:
- Adding a dimension to a cube doesn't multiply its memory footprint; the cube grows by the volume of new data, not by the volume of new theoretical space.
- An empty region of a cube - a market with rich data next to one that's mostly empty - costs nothing for the empty side.
- Cube design can be driven by what the business model needs, rather than by whether the resulting cube will be too sparse to perform.
Platforms that store or traverse every possible cell need active sparsity tuning as a routine part of model building. In MODLR that effort mostly isn't needed - the techniques above (restricting formulas, disabling feeders, removing unused data) cover the cases that do come up, and they're worth reaching for reactively when a specific cube or process is slow, not as preventive maintenance applied everywhere up front.
Dimension order
Every Cube has an internal dimension order, and Gateway provides a screen for reordering it after creation. The ideal order, when there's a genuine reason to change it, is small dense dimensions first, then large dense dimensions, then small sparse dimensions, then large sparse dimensions last - this helps the calculation engine traverse populated space efficiently.
Two things worth knowing before reordering:
- It's purely internal. The dimension order shown in Workviews, used by Excel
CubeGetformulas, and required by process functions likecube.setandcube.getis unaffected - reordering can't break an existing report or script. - It rarely moves the needle. The default order MODLR produces on cube creation is usually fine, and given how well sparsity is already handled, the gap between an optimal and a suboptimal order is often too small to matter. Reorder only after a specific performance issue has been traced to it, not as a first response to a slow cube.